OtherEN
Intro to Git — Snapshots, Branches & Sharing
 WorkshopyOfficial
10 stepsQuiz9 interactiveDiagram~65 min
gitversion controlbeginners
Used by 1 teacherBeginner
SQL GROUP BY exercises with answers: practise COUNT, SUM, AVG and HAVING on one sales table, and watch every row fall into its group.
WorkshopyOfficial
34 lessons · used by 2 teachers
Sign in to copy it to your workspace. It’s free.
14 steps · 2 quizzes · about 75 minutes · open any step, or read it here
In this lesson you practise SQL GROUP BY and aggregate functions on one small sales table: you group orders by region, rep and product, and count, total and average each group. Then you filter groups with HAVING, see how it differs from WHERE, and check your answers in exercises.
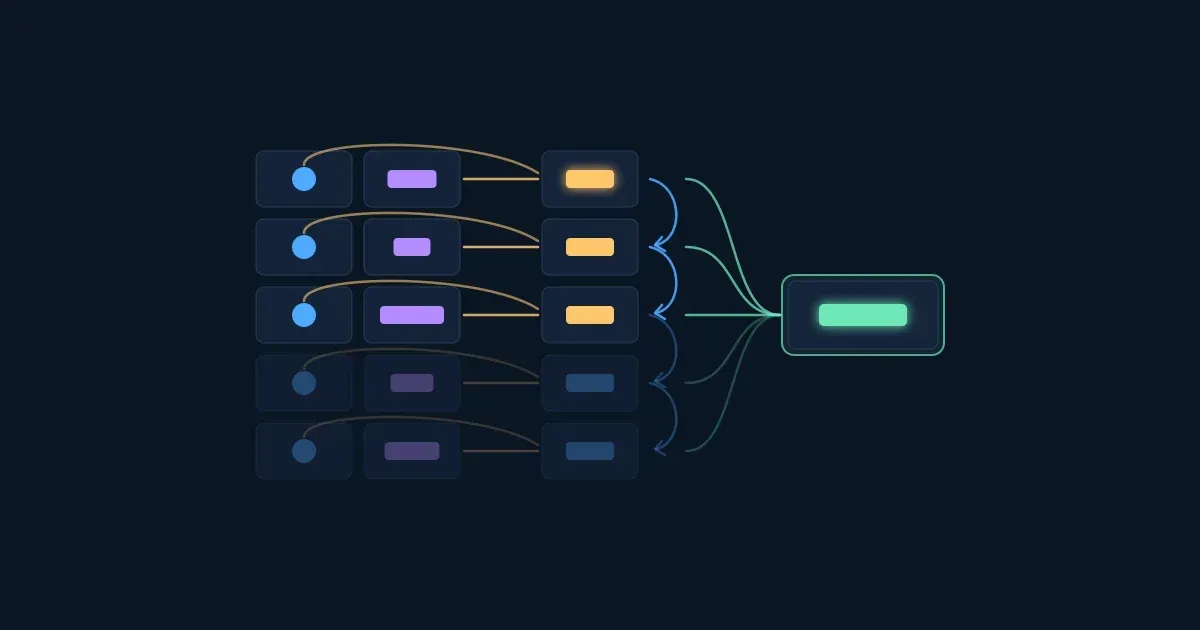
Here is the whole idea in one picture. Each card is one order. GROUP BY sorts the orders into buckets, one bucket per region, and the aggregate turns each bucket into a single number. Change the column or the function and watch the rows move.
Interactive · Rows fall into buckets, each bucket becomes one row — try it in the lesson
About 75 minutes, with a practice set halfway, a short check, a playground, a second practice set and a final quiz.
Here is the table the whole lesson uses: 14 orders, each sold by a rep in a region. Keep it in view; every answer in this lesson can be checked against it by hand.
| order_id | rep | region | product | amount | discount |
|---|---|---|---|---|---|
| 101 | Ana | North | Laptop | 1200 | 100 |
| 102 | Ben | South | Monitor | 300 | NULL |
| 103 | Ana | North | Monitor | 250 | NULL |
| 104 | Cara | East | Laptop | 1100 | 50 |
| 105 | Ben | South | Laptop | 1300 | NULL |
| 106 | Dev | North | Keyboard | 80 | NULL |
| 107 | Cara | East | Monitor | 330 | 20 |
| 108 | Ana | North | Keyboard | 90 | NULL |
| 109 | Ben | South | Keyboard | 70 | 20 |
| 110 | Dev | North | Laptop | 1250 | NULL |
| 111 | Cara | North | Keyboard | 70 | NULL |
| 112 | Ana | East | Laptop | 1150 | 80 |
| 113 | Eli | West | Monitor | 280 | NULL |
| 114 | Ben | South | Monitor | 310 | 30 |
An aggregate function reads a whole column of rows and returns one value. Five of them do almost all the work:
| Function | Returns | On amount |
|---|---|---|
COUNT(*) |
how many rows | 14 |
SUM(amount) |
the total | 7780 |
AVG(amount) |
the average (total ÷ count) | 555.71 |
MIN(amount) |
the smallest value | 70 |
MAX(amount) |
the largest value | 1300 |
SELECT COUNT(*), SUM(amount), AVG(amount), MIN(amount), MAX(amount)
FROM orders;
That query returns one row, however many rows the table has. With no GROUP BY, the whole table is a single bucket.
Try it: press each function and watch all 14 orders collapse into one value. For MIN and MAX, the order that holds the value is ringed just before the collapse. For MIN, two orders tie at 70.
Interactive · Five aggregate functions on the whole table — try it in the lesson
AVG(amount) is 7780 ÷ 14 = 555.714…, shown rounded. Databases print it with more decimals; ROUND(AVG(amount), 2) gives 555.71.
Takeaway: an aggregate turns a column of many values into one value.
One total for the whole company is rarely the question. Managers ask "how much did each region sell?" GROUP BY answers that: it puts every row into a bucket by the value of a column, one bucket for each different value.
SELECT region
FROM orders
GROUP BY region;
The orders table has four different regions, so there are four buckets: East (3 orders), North (6), South (4) and West (1). Each bucket becomes one row of the result, so this query returns 4 rows, not 14. GROUP BY with no aggregate gives the list of different values.
Try it: switch between region, rep and product. Count the buckets each time before the animation ends, then check the result table.
Interactive · Pick a column and watch the rows sort themselves into buckets — try it in the lesson
Grouping by rep makes 5 buckets (Ana, Ben, Cara, Dev, Eli). Grouping by product makes 3 (Keyboard, Laptop, Monitor). A bucket always holds at least one row: no row, no bucket.
Without ORDER BY, a database may return the buckets in any order. Here they come back sorted by name; ORDER BY, later in the lesson, lets you choose.
Takeaway: GROUP BY makes one bucket per different value, and each bucket becomes one result row.
Put the two ideas together. GROUP BY makes the buckets; an aggregate in SELECT then runs once per bucket, on that bucket's rows only.
SELECT rep, COUNT(*)
FROM orders
GROUP BY rep;
| rep | COUNT(*) |
|---|---|
| Ana | 4 |
| Ben | 4 |
| Cara | 3 |
| Dev | 2 |
| Eli | 1 |
Change COUNT(*) to SUM(amount) and the same five buckets give each rep's sales: Ana 2690, Ben 1980, Cara 1500, Dev 1330, Eli 280. Add up the five and you get 7780, the whole table's total: every row is in exactly one bucket.
You can put several aggregates side by side. Each is worked out on the same bucket:
SELECT region, COUNT(*), SUM(amount), AVG(amount)
FROM orders
GROUP BY region;
| region | COUNT(*) | SUM(amount) | AVG(amount) |
|---|---|---|---|
| East | 3 | 2580 | 860 |
| North | 6 | 2940 | 490 |
| South | 4 | 1980 | 495 |
| West | 1 | 280 | 280 |
Try it: choose a column and a function. Before you press, guess one value from the table above, then check it in the bucket.
Interactive · One value per bucket: choose the column and the function — try it in the lesson
North has the most orders (6) but the lowest average apart from West: many small keyboard orders pull it down. That is the kind of thing a per-group average shows and a single total hides.
Takeaway: the aggregate runs once per bucket, so the result has one row per group.
Work out each answer from the orders table, then check it. You can try the query in the step before.
| order_id | rep | region | product | amount | discount |
|---|---|---|---|---|---|
| 101 | Ana | North | Laptop | 1200 | 100 |
| 102 | Ben | South | Monitor | 300 | NULL |
| 103 | Ana | North | Monitor | 250 | NULL |
| 104 | Cara | East | Laptop | 1100 | 50 |
| 105 | Ben | South | Laptop | 1300 | NULL |
| 106 | Dev | North | Keyboard | 80 | NULL |
| 107 | Cara | East | Monitor | 330 | 20 |
| 108 | Ana | North | Keyboard | 90 | NULL |
| 109 | Ben | South | Keyboard | 70 | 20 |
| 110 | Dev | North | Laptop | 1250 | NULL |
| 111 | Cara | North | Keyboard | 70 | NULL |
| 112 | Ana | East | Laptop | 1150 | 80 |
| 113 | Eli | West | Monitor | 280 | NULL |
| 114 | Ben | South | Monitor | 310 | 30 |
SELECT region, SUM(amount) FROM orders GROUP BY region; What does it show for North?SELECT product, COUNT(*) FROM orders GROUP BY product; return?SELECT rep, COUNT(*) FROM orders GROUP BY rep; What is Cara's count?SELECT region, AVG(amount) FROM orders GROUP BY region; What is the average for South?SELECT rep, MAX(amount) FROM orders GROUP BY rep; Which rep has the largest single order?Sooner or later every analyst writes this query and gets an error:
SELECT region, rep, SUM(amount)
FROM orders
GROUP BY region;
PostgreSQL answers:
ERROR: column "orders.rep" must appear in the GROUP BY clause or be used in an aggregate function
The reason is in the buckets. The North bucket holds orders by Ana, Cara and Dev. North's result row has room for one rep, and SQL won't pick one for you. SQL Server refuses it too, and so does MySQL with its default setting (ONLY_FULL_GROUP_BY). SQLite and older MySQL settings run it and pick one rep's name from the bucket, which is worse: a quiet wrong answer.
The rule: every column in SELECT is either in GROUP BY or inside an aggregate. There are three ways to fix the query, depending on the question you meant to ask:
GROUP BY region, rep.COUNT(DISTINCT rep) says how many different reps sold there.Try it: run the broken query and look at the North bucket: three names, one row. Then press each fix and read what it answers. You can also edit the query and run it.
Interactive · Fix the query: one bucket, three reps — try it in the lesson
Takeaway: a bucket becomes one row, so every column you show must have one value per bucket.
With two columns in GROUP BY, a bucket is one combination of values. GROUP BY region, rep makes a bucket for each region and rep pair that appears in the data.
SELECT region, rep, COUNT(*), SUM(amount)
FROM orders
GROUP BY region, rep;
| region | rep | COUNT(*) | SUM(amount) |
|---|---|---|---|
| East | Ana | 1 | 1150 |
| East | Cara | 2 | 1430 |
| North | Ana | 3 | 1540 |
| North | Cara | 1 | 70 |
| North | Dev | 2 | 1330 |
| South | Ben | 4 | 1980 |
| West | Eli | 1 | 280 |
Seven buckets, not 4 × 5 = 20: only pairs that occur in some row get a bucket. Ana sold in North and East, so she has two buckets; Ben sold only in South, so he has one.
The order of the GROUP BY columns doesn't change the buckets. GROUP BY rep, region makes the same seven; only ORDER BY decides how they are sorted.
Try it: start from region, then switch to region, rep. Watch the North bucket split into three and the East bucket into two.
Interactive · Add a second GROUP BY column and the buckets split — try it in the lesson
GROUP BY region, product works the same way: 9 buckets, because 9 region and product pairs occur. North's laptops, for example, are orders 101 and 110: 2 orders, 2450.
Takeaway: with two GROUP BY columns, each combination that occurs is one bucket.
Only 6 of the 14 orders have a discount; the other 8 hold NULL, meaning "no value". Aggregates treat NULL in one simple way: every aggregate skips NULLs, except COUNT(*).
SELECT COUNT(*), COUNT(discount), COUNT(DISTINCT product),
       SUM(discount), AVG(discount)
FROM orders;
| COUNT(*) | COUNT(discount) | COUNT(DISTINCT product) | SUM(discount) | AVG(discount) |
|---|---|---|---|---|
| 14 | 6 | 3 | 300 | 50 |
COUNT(*) counts rows: 14.COUNT(discount) counts the rows where discount is not NULL: 6.COUNT(DISTINCT product) counts different values: Keyboard, Laptop, Monitor, so 3.AVG(discount) is 300 ÷ 6 = 50. It divides by the 6 rows that have a discount, not by 14. If a missing discount means "no discount", the average you want is 300 ÷ 14 ≈ 21.43, written AVG(COALESCE(discount, 0)). Decide what NULL means before you average.Try it: press each aggregate. Rows that the function skips turn amber and drop away before the bucket collapses. Then switch to GROUP BY region and look at West.
Interactive · What each COUNT counts, and what AVG skips — try it in the lesson
West's only order has no discount, so COUNT(discount) is 0 there, and SUM(discount) and AVG(discount) are NULL, not 0: there was nothing to add.
Takeaway: COUNT(*) counts rows; every other aggregate skips NULLs, and DISTINCT also skips repeats.
Use the orders table from the lesson.
Question 1. Without GROUP BY, how many rows does `SELECT COUNT(*), SUM(amount) FROM orders` return?
Question 2. Why does `SELECT region, rep, SUM(amount) FROM orders GROUP BY region` fail in PostgreSQL?
Question 3. How many rows does `SELECT region, rep, COUNT(*) FROM orders GROUP BY region, rep` return?
Question 4. `COUNT(*)` is 14 and `COUNT(discount)` is 6. Why?
WHERE is the filter you already know, and it keeps working the same way with GROUP BY: it looks at one row at a time and removes rows before any bucket exists. Only the rows that pass reach GROUP BY.
SELECT region, COUNT(*), SUM(amount)
FROM orders
WHERE amount > 1000
GROUP BY region;
| region | COUNT(*) | SUM(amount) |
|---|---|---|
| East | 2 | 2250 |
| North | 2 | 2450 |
| South | 1 | 1300 |
Five orders are over 1000, all laptops. West has none of them, so West has no bucket at all: a bucket only exists if some row reaches it.
Because WHERE runs before grouping, it can't use an aggregate. WHERE SUM(amount) > 2000 is an error: when WHERE runs, there is no sum yet. That is what HAVING is for, in the next step.
Try it: drag the slider. Rows that fail the condition move to the tray before the others fall into buckets. Find the value where West disappears, then the one where South does.
Interactive · WHERE removes rows before any bucket exists — try it in the lesson
Takeaway: WHERE removes rows first; the buckets and their totals are built only from what is left.
HAVING is a WHERE for buckets. It runs after GROUP BY, looks at one bucket at a time, and keeps or removes the whole bucket. Because the buckets exist by then, HAVING can use aggregates.
SELECT region, SUM(amount)
FROM orders
GROUP BY region
HAVING SUM(amount) > 2000;
| region | SUM(amount) |
|---|---|
| East | 2580 |
| North | 2940 |
South (1980) and West (280) are removed. Their rows were all grouped and totalled; HAVING then threw the totals away.
HAVING can test any aggregate, even one that is not in SELECT. "Reps with more than 3 orders":
SELECT rep, COUNT(*)
FROM orders
GROUP BY rep
HAVING COUNT(*) > 3;
That returns Ana (4) and Ben (4). Cara has exactly 3, and 3 is not more than 3.
Write the aggregate itself in HAVING (HAVING SUM(amount) > 2000), not a name you gave it in SELECT. MySQL and SQLite accept the name; PostgreSQL and SQL Server don't.
Try it: drag the threshold and watch buckets fade out, whole. Switch to rep and find the threshold that leaves only Ana.
Interactive · HAVING keeps or removes whole buckets — try it in the lesson
Takeaway: HAVING keeps or removes whole buckets, using their aggregates.
WHERE and HAVING both filter, so they are easy to mix up. Compare two queries that both say "over 1000":
-- WHERE: only orders over 1000 are added up
SELECT region, SUM(amount) FROM orders
WHERE amount > 1000
GROUP BY region;

-- HAVING: every order is added up, then regions over 1000 are kept
SELECT region, SUM(amount) FROM orders
GROUP BY region
HAVING SUM(amount) > 1000;
| region | WHERE amount > 1000 | HAVING SUM(amount) > 1000 |
|---|---|---|
| East | 2250 | 2580 |
| North | 2450 | 2940 |
| South | 1300 | 1980 |
Both return three regions, and West is gone from both, but the numbers differ. WHERE answered "how much did each region sell in large orders?" HAVING answered "which regions sold more than 1000 in total, and how much?"
You can use both in one query: WHERE trims the rows, then HAVING trims the buckets. "Regions whose large orders add up to more than 2000" keeps North (2450) and East (2250).
Try it: switch between the four filters. Watch where the filtering happens: rows going to the tray (WHERE), or whole buckets fading (HAVING).
Interactive · WHERE amount > 1000 or HAVING SUM(amount) > 1000 — try it in the lesson
A rule of thumb: if the condition is about one row (amount, product, region), it goes in WHERE. If it is about a group (a count, a total, an average), it goes in HAVING. A row condition in WHERE is usually faster too: fewer rows to group.
Takeaway: WHERE filters rows before grouping; HAVING filters buckets after it.
You write a query starting with SELECT, but the database runs the clauses in a different order:
This order explains most of the rules in this lesson. WHERE can't use an aggregate because buckets don't exist yet. WHERE can't use a name from SELECT, because SELECT hasn't run. ORDER BY runs after SELECT, so it can sort by a name like total, or by an aggregate:
SELECT rep, SUM(amount) AS total
FROM orders
WHERE product <> 'Keyboard'
GROUP BY rep
HAVING COUNT(*) >= 2
ORDER BY total DESC
LIMIT 2;
| rep | total |
|---|---|
| Ana | 2600 |
| Ben | 1910 |
Try it: press Next clause and follow the query from FROM to ORDER BY. The clause that runs is marked in the query. Before each press, say what will happen to the rows.
Interactive · Run a query one clause at a time — try it in the lesson
Walk through it: WHERE removes the four keyboard orders, GROUP BY makes five rep buckets, HAVING removes Dev and Eli (one order each), SELECT totals the rest, ORDER BY puts Ana (2600) first, and LIMIT 2 cuts Cara (1430).
Takeaway: FROM, WHERE, GROUP BY, HAVING, SELECT, ORDER BY: each clause only sees what the one before it left.
Now write the queries yourself. The playground knows the orders table and its six columns: order_id, rep, region, product, amount, discount. It understands COUNT, SUM, AVG, MIN, MAX, DISTINCT, WHERE, GROUP BY, HAVING, ORDER BY and LIMIT, and gives the same errors a real database would.
Try it: answer these, one query each.
Interactive · GROUP BY playground on the orders table — try it in the lesson
If you get an error, read it: it names the clause and the column, and the fix is usually one of the three from the "must appear in the GROUP BY clause" step.
Takeaway: you can now answer "how much, how many, for each" questions with one query.
Work out each answer, then check it. The playground in the step before runs any of these queries.
| order_id | rep | region | product | amount | discount |
|---|---|---|---|---|---|
| 101 | Ana | North | Laptop | 1200 | 100 |
| 102 | Ben | South | Monitor | 300 | NULL |
| 103 | Ana | North | Monitor | 250 | NULL |
| 104 | Cara | East | Laptop | 1100 | 50 |
| 105 | Ben | South | Laptop | 1300 | NULL |
| 106 | Dev | North | Keyboard | 80 | NULL |
| 107 | Cara | East | Monitor | 330 | 20 |
| 108 | Ana | North | Keyboard | 90 | NULL |
| 109 | Ben | South | Keyboard | 70 | 20 |
| 110 | Dev | North | Laptop | 1250 | NULL |
| 111 | Cara | North | Keyboard | 70 | NULL |
| 112 | Ana | East | Laptop | 1150 | 80 |
| 113 | Eli | West | Monitor | 280 | NULL |
| 114 | Ben | South | Monitor | 310 | 30 |
SELECT region, SUM(amount) FROM orders WHERE amount > 1000 GROUP BY region; What does it show for North?SELECT region, SUM(amount) FROM orders GROUP BY region HAVING SUM(amount) > 2000; return?SELECT region, COUNT(discount) FROM orders GROUP BY region; What does it show for North?SELECT AVG(discount) FROM orders; return?Use the orders table from the lesson.
Question 1. Which clause filters whole groups after GROUP BY has made them?
Question 2. In which order does the database run these clauses?
Question 3. Which queries run in PostgreSQL? (pick all that apply)
Question 4. What does `SELECT region, SUM(amount) FROM orders WHERE amount > 1000 GROUP BY region HAVING SUM(amount) > 2000` return?
Question 5. What does `SELECT COUNT(DISTINCT product) FROM orders` return?
Question 6. `SELECT region, AVG(discount) FROM orders GROUP BY region`: what does it show for West?
Workshopy shares this lesson under CC BY 4.0. Anyone may use and change it, with credit to you. Anyone can learn it here, free. A copy in your workspace is yours to change and run live; your students never need an account.
Version 1Current
· First published
Copies are made from the current version. A copy you already have doesn’t change.
WorkshopyOfficial10 stepsQuiz9 interactiveDiagram~65 min
gitversion controlbeginners
WorkshopyOfficial16 steps2 quizzes15 interactiveDiagram~120 min
workshopyproduct touronboarding
WorkshopyOfficial9 steps2 quizzes8 interactive~60 min
excelspreadsheetsformulas
WorkshopyOfficial10 steps2 quizzes9 interactive~60 min
sqljoindatabases
WorkshopyOfficial10 steps2 quizzes9 interactive~70 min
sqldatabasesdata analysis
WorkshopyOfficial12 steps2 quizzes12 interactive~85 min
data literacystatisticscharts
Comments
No comments yet. Be the first to say how it went.