
OtherEN
Intro to Git — Snapshots, Branches & Sharing
 WorkshopyOfficial
10 stepsQuiz9 interactiveDiagram
gitversion controlbeginners
Used by 1 teacherBeginner
Pandas exercises for beginners: load a sales CSV as a DataFrame, filter, group, sort and chart it, side by side with Excel, with exercises you check.
WorkshopyOfficial
78 lessons · used by 2 teachers
Sign in to copy it to your workspace. It’s free.
9 steps · 2 quizzes · open any step, or read it here
This pandas for beginners lesson starts with a question every spreadsheet user meets: which region sold the most? In Excel you would filter, build a pivot table and sort; in Python, pandas answers it in a few short lines that work the same on twelve rows or a hundred thousand.
Interactive · Which region sold the most? From spreadsheet to answer — try it in the lesson
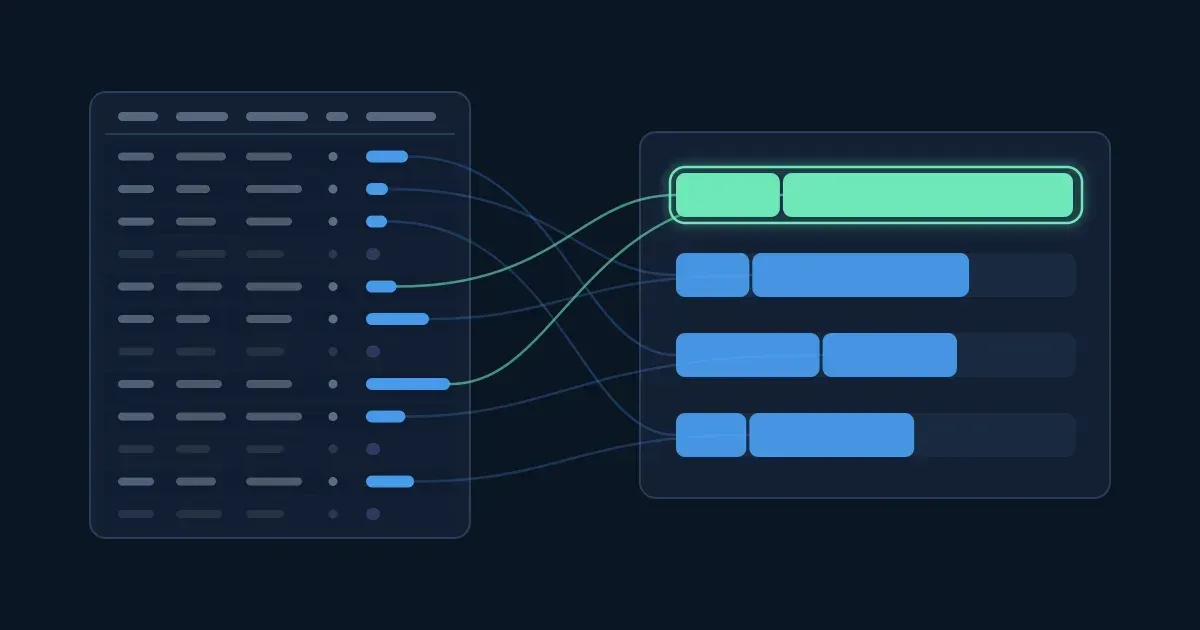
You just watched a table of orders become an answer: a filter dimmed the small orders, each region's revenue stacked into one bar, and the bars sorted themselves. By the end of this lesson you will write the pandas code that does exactly that.
What you need: a browser. A little Python helps (variables, lists, calling a function); nothing needs installing.
pandas is a Python library for working with tables. Its table is called a DataFrame: rows and named columns, like one sheet in Excel. The whole lesson uses one small file, sales.csv: twelve orders from an imaginary shop (illustrative numbers).
order_id,region,product,units,revenue
1001,North,Laptop,2,2400
1002,South,Monitor,5,1250
1003,East,Laptop,1,1200
1004,North,Mouse,10,250
1005,West,Monitor,7,1750
1006,South,Laptop,3,3600
1007,East,Mouse,8,200
1008,West,Laptop,4,4800
1009,North,Monitor,9,2250
1010,South,Mouse,6,150
1011,East,Monitor,11,2750
1012,West,Mouse,12,300
Three lines read it and show the start:
import pandas as pd

df = pd.read_csv("sales.csv")
df.head()
pd is the short name everyone gives pandas. read_csv turns the file into a DataFrame, which we call df, and head() shows its first five rows:
   order_id region  product  units  revenue
0      1001  North   Laptop      2     2400
1      1002  South  Monitor      5     1250
2      1003   East   Laptop      1     1200
3      1004  North    Mouse     10      250
4      1005   West  Monitor      7     1750
Three differences from Excel matter from the start:
df["region"], not "column B".Try it: press the buttons, or click any cell on either side, and see where the same thing lives in the other view.
Interactive · Excel and pandas, side by side — try it in the lesson
Two more you will use all the time: df.shape prints (12, 5), twelve rows and five columns, and df.tail() shows the last five rows. In a notebook (Jupyter, Google Colab) the last line of a cell is shown by itself; in a .py script, wrap it in print().
Takeaway: a DataFrame is your sheet, with column names instead of letters and an index instead of row numbers.
A sheet with fifty columns is hard to read. pandas lets you keep only the ones you need:
df["revenue"], single brackets. You get a Series: one column with its index.df[["region", "revenue"]], double brackets. The inner pair is a Python list of names, and you get a smaller DataFrame with the columns in the order you listed.In Excel, a new column is a formula in the first cell, filled down. In pandas, one line does every row at once:
df["price"] = df["revenue"] / df["units"]
pandas divides row by row: 2400 / 2 for the first order, 1250 / 5 for the second, and so on. The result prints as 1200.0 because / always gives decimals in Python.
Try it: do the three tasks. Watch the code change with every click.
Interactive · Pick columns and add one — try it in the lesson
What happened when you picked two columns with single brackets? df["region", "revenue"] asks for ONE column whose name is the pair, and there is none: a KeyError.
Takeaway: df["col"] is one column, df[["a", "b"]] is a smaller table, and df["new"] = … fills a whole column in one line.
In Excel you would click the filter arrow on the region column and tick South. In pandas you write the condition:
df[df["region"] == "South"]
Read it from the inside out. df["region"] == "South" compares every row and gives one True or False per row: a mask. df[mask] keeps the rows where the mask is True.
   order_id region  product  units  revenue
1      1002  South  Monitor      5     1250
5      1006  South   Laptop      3     3600
9      1010  South    Mouse      6      150
The rules:
== compares; a single = would assign. Text goes in quotes, numbers don't.!=, >, >=, < and <= mean what they mean in Excel.& for "and", | for "or", and each condition in its own parentheses. Python's own and / or don't work on a whole column: pandas stops with "The truth value of a Series is ambiguous".df[df["region"].isin(["South", "West"])].Try it: build the three filters. Watch the mask: one True or False per row.
Interactive · Build a filter and watch the mask — try it in the lesson
The third filter in code:
df[(df["product"] == "Mouse") & (df["units"] >= 10)]
    order_id region product  units  revenue
3       1004  North   Mouse     10      250
11      1012   West   Mouse     12      300
Takeaway: a filter is a mask of True and False inside df[...]; join conditions with & or |, each in parentheses.
Four questions on the steps so far. Use sales.csv as in the lesson.
Question 1. What does `df.shape` print for sales.csv?
Question 2. Which line gives a DataFrame with only the region and revenue columns?
Question 3. In `df[df["revenue"] > 1000]`, what does the inner part `df["revenue"] > 1000` make?
Question 4. The first order has index label 0 in pandas. Which Excel row holds it when you open sales.csv?
Now the question from the start: total revenue per region. In Excel you would build a PivotTable (region in Rows, Sum of revenue in Values) or write a SUMIFS for each region. In pandas:
df.groupby("region")["revenue"].sum()
Read it left to right: split the rows into groups by region, take each group's revenue, add it up.
region
East     4150
North    4900
South    5000
West     6850
Name: revenue, dtype: int64
The answer is a Series: the group names became its index, and they come out A to Z, because groupby sorts its groups by name. To put the biggest first, chain one more move, .sort_values(ascending=False). To sum only some orders, put a filter in front. With one move per line, inside parentheses, it reads like a recipe:
(df[df["revenue"] > 1000]
   .groupby("region")["revenue"]
   .sum()
   .sort_values(ascending=False))
Try it: pick a filter and a column to group by, press Run, then switch the sort off and on. Each kept row's revenue becomes a block on its group's bar, so the bar's length is the sum.
Interactive · Filter, group, sum and sort: the question in one chain — try it in the lesson
Which region wins with all rows? Does the winner change when only orders over 1000 count? And which product brings in the most?
sum() is one of several: .mean(), .count(), .max() and .min() work the same way, and .agg() gives several at once:
df.groupby("region")["revenue"].agg(["sum", "mean", "count"])
         sum         mean  count
region
East    4150  1383.333333      3
North   4900  1633.333333      3
South   5000  1666.666667      3
West    6850  2283.333333      3
Takeaway: df.groupby("col")["value"].sum() is a pivot table in one line; filter before it, sort after it.
Excel's "Sort Largest to Smallest" is sort_values:
df.sort_values("revenue", ascending=False).head(3)
    order_id region  product  units  revenue
7       1008   West   Laptop      4     4800
5       1006  South   Laptop      3     3600
10      1011   East  Monitor     11     2750
ascending=False puts the biggest first; leave it out for smallest first..head(3) keeps the first three rows of the result, so sort first, then cut: df.head(3).sort_values(...) would only sort the file's first three rows.df.nlargest(3, "revenue") is a shortcut for the same top three.df.sort_values("region"). Rows with the same value (three orders per region) can come out in any order between them; add kind="stable" to keep the file's order.Try it: three sorts, and watch the rows move.
Interactive · Sort the orders and keep the top — try it in the lesson
Takeaway: sort_values(column, ascending=False) then .head(n) gives you the top n.
A sorted Series of totals is one line away from a chart. pandas draws it with matplotlib, the standard Python charting library:
revenue = df.groupby("region")["revenue"].sum().sort_values(ascending=False)
revenue.plot(kind="bar", title="Revenue by region")
Each index label becomes a bar, each value its height. In Jupyter or Colab the chart appears under the cell; in a .py script, add import matplotlib.pyplot as plt at the top and plt.show() at the end. kind can be "bar", "barh" (horizontal), "pie" or "line" (for numbers over time).
Try it: switch between the kinds and the two groupings, and turn the sort off. The chart below is drawn in your browser the way pandas would draw it.
Interactive · One line from totals to a chart — try it in the lesson
Notice what "barh" does with a list sorted biggest first: the first row goes at the bottom. For the biggest bar on top, sort with ascending=True before a horizontal chart.
Takeaway: sort, then .plot(kind=...): a sorted chart answers "which is biggest" at a glance.
Everything so far, side by side:
| The question | In Excel | In pandas |
|---|---|---|
| Open the data | Open sales.csv | df = pd.read_csv("sales.csv") |
| How big is it? | Scroll, or Ctrl+End | df.shape |
| Only some columns | Hide the others | df[["region", "revenue"]] |
| A new column | =E2/D2, filled down |
df["price"] = df["revenue"] / df["units"] |
| Only some rows | Filter arrow, or =FILTER(A2:E13, B2:B13="South") |
df[df["region"] == "South"] |
| A total for one group | =SUMIFS(E2:E13, B2:B13, "South") |
df[df["region"] == "South"]["revenue"].sum() |
| Totals for every group | PivotTable | df.groupby("region")["revenue"].sum() |
| Biggest first | Sort Largest to Smallest | .sort_values(ascending=False) |
| The top 3 | Sort, then read three rows | .head(3) or df.nlargest(3, "revenue") |
| A chart | Insert, Chart | .plot(kind="bar") |
The difference is not speed on twelve rows. It is that the pandas version is written down: run it again next month on a new file and you get the new answer, with nobody clicking through the same steps again.
Open Google Colab, choose New notebook, paste this into a cell and press Run. The file sits inside the code, so there is nothing to upload.
import pandas as pd
from io import StringIO

csv = """order_id,region,product,units,revenue
1001,North,Laptop,2,2400
1002,South,Monitor,5,1250
1003,East,Laptop,1,1200
1004,North,Mouse,10,250
1005,West,Monitor,7,1750
1006,South,Laptop,3,3600
1007,East,Mouse,8,200
1008,West,Laptop,4,4800
1009,North,Monitor,9,2250
1010,South,Mouse,6,150
1011,East,Monitor,11,2750
1012,West,Mouse,12,300"""

df = pd.read_csv(StringIO(csv))
print(df.groupby("region")["revenue"].sum().sort_values(ascending=False))
Then add a line of your own that answers: how many mice were sold in all, across every order? (print(...) around it shows a clean number.)
Check your work · Paste the number your line printed: the total units of all Mouse orders. — check it in the lesson
Takeaway: every Excel move you know has a one-line pandas twin, and the pandas version can be run again on next month's file.
Six exercises on sales.csv, the twelve orders from the lesson. Work each one out from the data, then check. A hint costs nothing.
df[df["units"] >= 5] keep?df[df["region"] == "East"]["revenue"].sum() print?df.groupby("product")["units"].sum() prints one line per product. What number is on the Mouse line?df[df["product"] == "Laptop"]["units"].mean() print?df.groupby("region")["revenue"].sum().sort_values(ascending=False)df.groupby("revenue")["region"].sum()df.sort_values("revenue").groupby("region")["revenue"].sum()df["revenue"].sum().sort_values(ascending=False)df[(df["region"] == "North") & (df["units"] > 3)]df[df["region"] == "North" & df["units"] > 3]df[(df["region"] == "North") and (df["units"] > 3)]df[(df["region"] == "North") | (df["units"] > 3)]Six questions on the whole lesson. One of them has more than one right answer.
Question 1. `df.groupby("region")["revenue"].sum()` lists the regions in which order?
Question 2. Which lines keep only the orders from the South or the West? (pick all that apply)
Question 3. Which line gives the three orders with the highest revenue?
Question 4. Which pandas line gives the same number as `=SUMIFS(E2:E13, B2:B13, "South")`?
Question 5. After `df[df["revenue"] > 2000]`, what are the index labels of the rows that stay?
Question 6. You sort the region totals biggest first and plot them with `kind="barh"`. Where is the biggest bar?
Workshopy shares this lesson under CC BY 4.0. Anyone may use and change it, with credit to you. Anyone can learn it here, free. A copy in your workspace is yours to change and run live; your students never need an account.
Version 1Current
· First published
Copies are made from the current version. A copy you already have doesn’t change.
WorkshopyOfficial10 stepsQuiz9 interactiveDiagram
gitversion controlbeginners
WorkshopyOfficial16 steps2 quizzes15 interactiveDiagram
workshopyproduct touronboarding
WorkshopyOfficial10 steps2 quizzes10 interactive
data-literacystatisticsmean and median
WorkshopyOfficial11 steps2 quizzes10 interactive
data-literacycorrelationcausation
WorkshopyOfficial10 steps2 quizzes9 interactive
excelsumifcountif
WorkshopyOfficial11 steps2 quizzes10 interactive
sqlwindow functionsdata analysis


Comments
No comments yet. Be the first to say how it went.